AI
DFlash: A Breakthrough in LLM Inference with Speculative Decoding on NVIDIA Blackwell
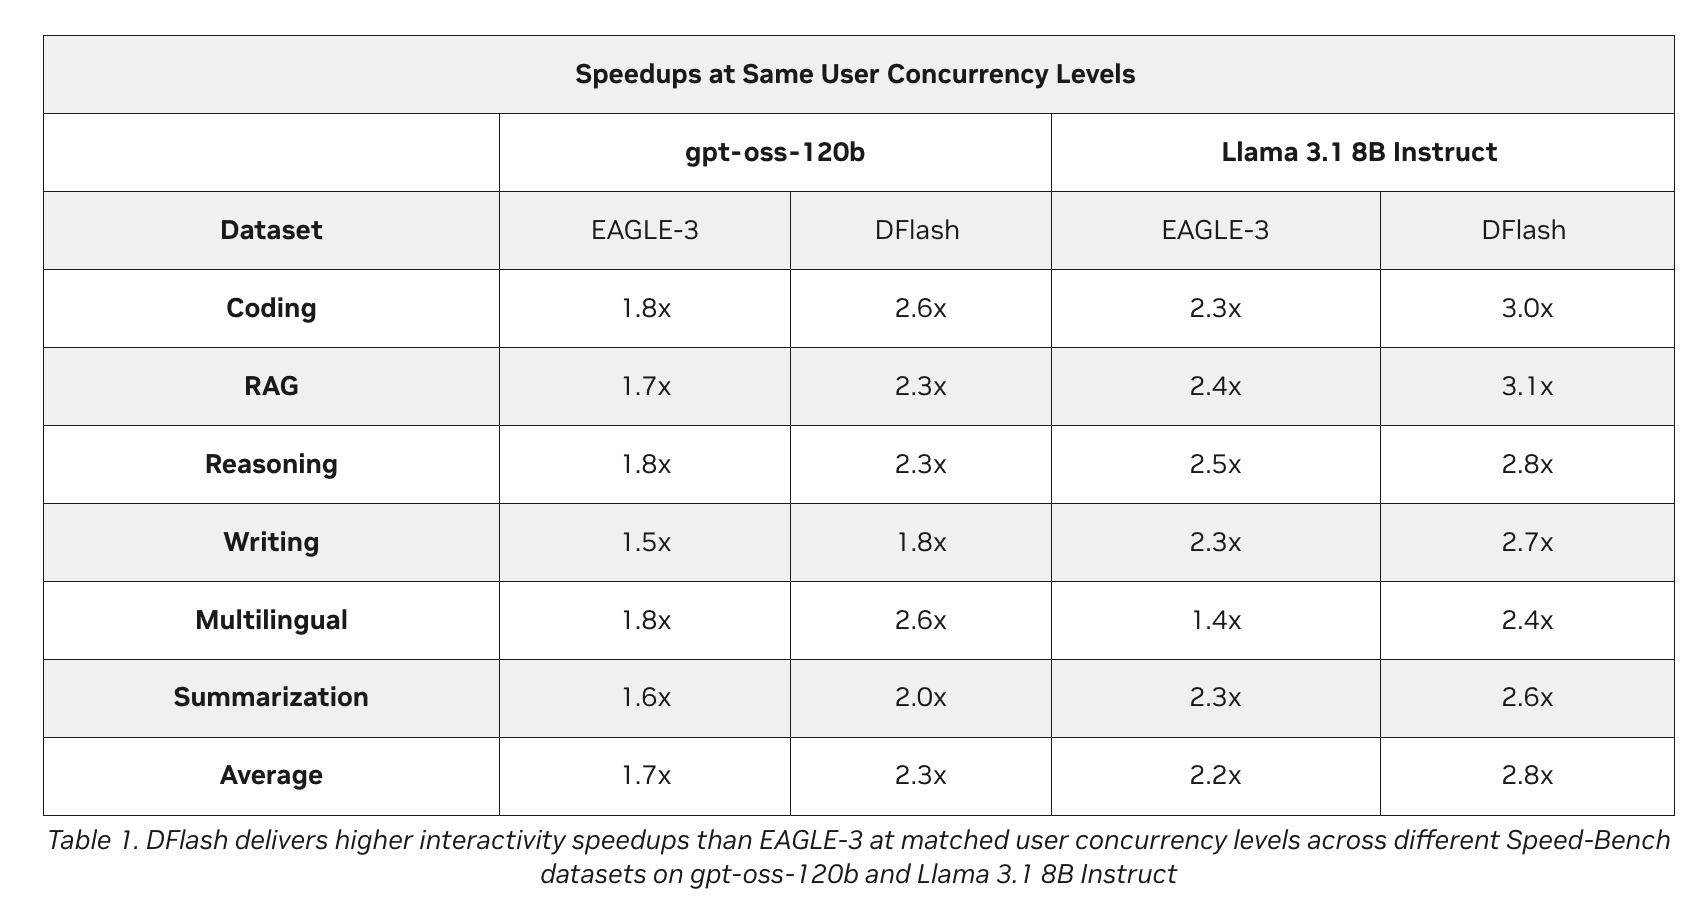
DFlash, developed by UC San Diego, introduces a block diffusion model for speculative decoding, replacing autoregressive generation. This method enables the drafting of entire blocks of tokens in a single forward pass, conditioning hidden features via KV injection. Preliminary results report up to 6.08x lossless acceleration on Qwen3-8B and a peak throughput of 15x on NVIDIA Blackwell architectures.
Carlos "Emérito" López Lovera