The inference of large language models (LLMs) presents a significant computational challenge, especially in scenarios demanding high efficiency and low latency. The predominant method of autoregressive decoding, which generates tokens sequentially, imposes an inherent bottleneck on throughput and latency, limiting the scalability and economic viability of intensive AI applications.
Technical Context: Speculative Decoding and its Optimizations
Speculative decoding emerged as a technique to mitigate these limitations. It involves using a smaller, faster draft model to generate a sequence of candidate tokens, which are then verified in parallel by the large model. If the tokens are correct, they are accepted; otherwise, the process reverts to the last accepted token and continues generation. Although this technique improves speed, the draft models used to date have often also been autoregressive, which, while faster, still do not fully exploit potential parallelism.
DFlash Innovation in Parallel Token Generation
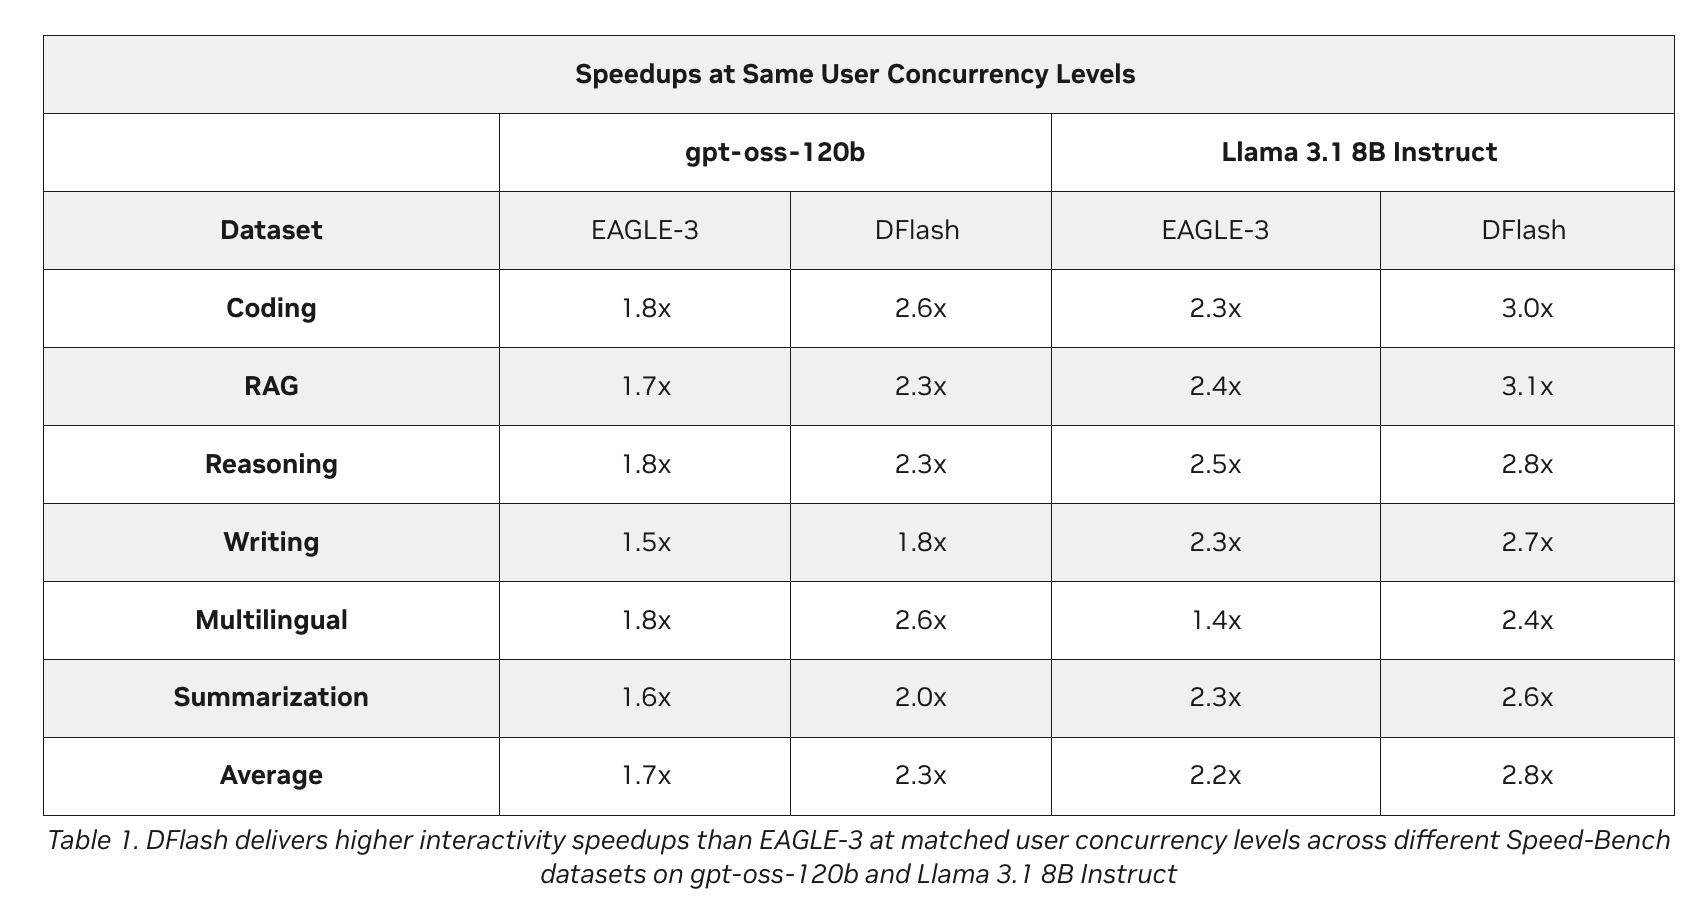
DFlash, a proposal from UC San Diego, redefines speculative decoding by replacing the autoregressive draft model with a lightweight block diffusion model. This innovation allows DFlash to generate complete blocks of tokens in a single forward pass, rather than token by token. The technical key lies in its ability to condition the hidden features of the target model through KV (Key-Value) injection. This mechanism ensures that the drafts generated by the block diffusion model are contextually relevant and high-quality, maximizing the acceptance rate by the main model without sacrificing accuracy.
Impact on Performance and NVIDIA Blackwell Architecture
Preliminary results are remarkable. DFlash has demonstrated lossless acceleration of up to 6.08x on the Qwen3-8B model. The projection of up to 15x greater throughput specifically refers to its implementation and optimization on the NVIDIA Blackwell architecture. The Blackwell series, designed for next-generation AI workloads, incorporates parallel processing capabilities and advanced memory that DFlash can efficiently exploit. This synergy between the optimized algorithm and high-performance hardware is crucial for achieving such levels of efficiency.
Economic and Operational Implications
The implications of DFlash are significant for the AI ecosystem. An improvement of up to 15 times in inference throughput directly translates into a substantial reduction in operational costs for LLM service providers. Companies deploying large-scale AI models will be able to serve a greater number of users with the same infrastructure or reduce hardware investment to maintain current service levels. This democratizes access to advanced AI, making LLM execution more accessible and economically viable for a broader spectrum of applications and businesses. Furthermore, lower latency opens the door to new real-time applications that were previously unfeasible, such as highly responsive virtual assistants, dynamic content generation systems, or more fluid and natural human-machine interfaces.
The optimization of LLM inference remains an active field of research and development. The adoption of techniques like DFlash in large-scale production environments will determine its long-term impact on the AI economy. It will be crucial to monitor the deployment of these innovations on cloud platforms and API services to evaluate their widespread adoption and their ability to transform AI inference infrastructure.